1. Extractable text
Character strings present in the file (text layer of a PDF, annotations of a DXF).
RAGatm Open is first a text platform. The published code contains extractors for images, scanned PDFs, technical drawings, building models and audio, but most are disabled or incomplete in the Open edition. This page distinguishes each case.
For each content type, the site distinguishes what the code actually produces.
Character strings present in the file (text layer of a PDF, annotations of a DXF).
Lines, polylines, arcs… In the Open edition they are counted but never indexed.
Headings, tables, slides, layers, IFC spatial hierarchy: kept as typed blocks with a locator for citations.
Interpreting a diagram, a legend, a 3D view. No component of the Open edition does this.
Possible only for levels 1 and 3; the answer then cites the text or the structure, not the drawing.
What happens to images, scanned PDFs and visual descriptions.
| Feature | Status | Description and limits | Details |
|---|---|---|---|
| Native tables (PDF, DOCX, PPTX, XLSX) | Enabled by default | PDF: only the pile_head_forces table type is extracted structurally (always on); generic PDF tables behind a flag (off); DOCX flattened 'cell | cell'; PPTX as Markdown; XLSX as structured chunks with sheet+range locator. Generic PDF tables partial and off; Office chart data off; XLSX images/charts ignored. | Details
|
| DXF: documentary extraction (text, attributes) | Configurable | ezdxf installed; TEXT/MTEXT/DIMENSION/MULTILEADER annotations by layout+layer and block ATTRIB; geometric entities only counted; flag closed by default. Text: yes; geometry: counted only, never indexed; structure: layers/blocks; semantic understanding: no; RAG grounding: annotations only. | Details
|
| PDF OCR (local Tesseract) | Optional | OCR of textless PDF pages via pytesseract + pypdfium2 (fra+eng, auto-rotate, ≤50 pages, 60 s/page); off in code and Compact; Compact image built without Tesseract (WITH_OCR=0). Single engine without fallback; OCR text classed "other" (never numeric proof); without OCR a scanned PDF fails (pdf_scanned_requires_ocr). | Details
|
| Standalone image OCR | Optional | JPEG/PNG/TIFF/WEBP images accepted and systematically OCRed by Tesseract; in Compact the image is accepted then fails ocr_engine_missing. In Compact: clean failure, no text extracted from images. | Details
|
| Multilingual OCR | Optional | Configurable Tesseract languages (default fra+eng; WITH_OCR image installs tesseract-ocr-fra/eng). Other languages require extra Tesseract packages in a custom image. | Details
|
| Image description by a vision model | Optional | POST /v1/vision/analyze (task describe) producing an indexed text description; off on RAGatm and Gateway; no vision model in the Compact registry; ingest_visual queue has no consumer in Compact. The description is text, not value extraction; unreachable in Compact (no vision model). | Details
|
| Visual enrichment of inline images | Optional | Discovery of inline PDF/DOCX/PPTX images then deferred Vision description; PDF discovery needs PyMuPDF (AGPL, not installed); DOCX/PPTX never qualified against a real Gateway. Vision on PDF inline images impossible with the default Open image. | Details
|
| DWG via LibreDWG | Optional | DWG→DXF conversion by the GPL dwg2dxf executable (subprocess) then DxfExtractor; build option WITH_DWG=1 and ingest_dwg worker; not built in Compact. Same limits as DXF; separate GPL executable. | Details
|
| IFC / BIM: semantic extraction | Optional | Spatial hierarchy, elements, properties, quantities, materials via ifcopenshell (ifc extra, ~147 MB); no geometry or coordinates; ingest_ifc worker required; not built in Compact. Text/attributes: yes; geometry: no; 3D: no; semantics: schema-level attributes only. | Details
|
| Curve digitisation (internal experiment) private edition only | Experimental | Experimental curve digitisation run in shadow mode; nothing is published to the index. Internal experiment depending on an absent module. | Details
|
| Region-based vision (internal experiment) private edition only | Experimental | Experimental V2 orchestration (pdfium render, region crops), empty allowlist, no fragment produced. Internal experiment. | Details
|
| Understanding of charts, diagrams and technical drawings | Not yet qualified | Gateway tasks table/diagram/chart/technical_drawing exist in the schema but are not qualified (400 vision_task_not_qualified); charts and drawings get at most a description; no series values or structured relations. Text: via description only; geometry: no; structure: no; semantic understanding: no; RAG grounding: description text only. | Details
|
| Local layout-analysis service (hybrid rail) | Not yet qualified | Hybrid rail to a local layout-analysis service (loopback), max 3 pages per document; not qualified, absent from Compact. No particular limit noted. | Details
|
| PDF vector figures | Not yet qualified | Rendering of PDF vector regions (PyMuPDF) then description; flag and space allowlist; visual extraction not retained. Requires PyMuPDF, absent from the Open image. | Details
|
| Gateway vision API endpoints | Disabled | POST /v1/vision/analyze, GET /v1/vision/capacity, GET /health/vision exist (OllamaVisionBackend); disabled (503 vision_not_enabled); semantic_extract excluded from the Open edition. Only description is qualified; no OCR in the gateway. | Details
|
| OCR of embedded images (PDF/DOCX/PPTX) | Unavailable | No OCR is applied to images embedded in PDF/DOCX/PPTX; only author-typed alt text is read for slides. No particular limit noted. | Details
|
| Structured layout extraction (external module) private edition only | Unavailable | Structured-extraction route (tables → rows/cells, charts → series): client present in RAGatm, but the route is absent from the Open gateway (404) and the module is not included. External structured-extraction module, absent from the Open edition. | Details
|
| Geometry, 3D rendering, legends | Unavailable | No graphical rendering, no indexed geometry, no legend understanding for CAD/BIM formats; image-based plans/diagrams get at most a Vision description (if enabled). No particular limit noted. | Details
|
| Format | Status | OCR | Limits |
|---|---|---|---|
| Scanned / image-only PDF (OCR) | Optional | no | Upload accepted (valid PDF) but ingestion fails in Compact (pdf_scanned_requires_ocr). With an image rebuilt with OCR: local Tesseract only, 50 pages maximum, 60 s per page, fra+eng languages; table reconstruction from OCR is experimental and not qualified. |
| JPEG image | Optional | no | Accepted at upload (DOCUMENT_IMAGE_INGEST_ENABLED=1 by default), but extraction relies on OCR only: in Compact (WITH_OCR=0) ingestion fails with ocr_engine_missing. No visual description by a vision model in the Open edition. |
| PNG image | Optional | no | Accepted at upload (DOCUMENT_IMAGE_INGEST_ENABLED=1 by default), but extraction relies on OCR only: in Compact (WITH_OCR=0) ingestion fails with ocr_engine_missing. No visual description by a vision model in the Open edition. |
| TIFF image | Optional | no | Accepted at upload (DOCUMENT_IMAGE_INGEST_ENABLED=1 by default), but extraction relies on OCR only: in Compact (WITH_OCR=0) ingestion fails with ocr_engine_missing. No visual description by a vision model in the Open edition. |
| WEBP image | Optional | no | Accepted at upload (DOCUMENT_IMAGE_INGEST_ENABLED=1 by default), but extraction relies on OCR only: in Compact (WITH_OCR=0) ingestion fails with ocr_engine_missing. No visual description by a vision model in the Open edition. |
| GIF image | Disabled | no | Detected by signature but refused (image_unsupported_format): not in the default DOCUMENT_IMAGE_FORMATS list. Adding it also requires an OCR-enabled image build. |
| BMP image | Disabled | no | Detected by signature but refused (image_unsupported_format): not in the default DOCUMENT_IMAGE_FORMATS list. Adding it also requires an OCR-enabled image build. |
Tables are extracted from several formats; charts are not recognised.
| Format | Status | Tables | Layout | Limits |
|---|---|---|---|---|
| PDF (text layer) | Enabled by default | partial | partial | pypdf engine with pdfminer/pdfplumber fallback. 500 pages and 180 s extraction budget maximum. Tables: only recognised table types are extracted by default; generic grids need a flag and a space allowlist. Embedded images are never extracted in Compact. Scanned PDFs fail without OCR. |
| Word (.docx) | Enabled by default | yes | partial | Document body only: headers, footers, footnotes and text boxes are not extracted. Tables linearised. Embedded images ignored. Citations without page number (unpaginated format). |
| Excel (.xlsx) | Enabled by default | yes | partial | Documentary ingestion only: cells rendered in windows (40 rows) with sheet/range provenance; no calculation or formula evaluation. Limits: 1,000,000 cells, 100 sheets, 256 columns. Images ignored. |
| PowerPoint (.pptx) | Enabled by default | yes | partial | One unit per slide (citations by slide number). Tables rendered as Markdown. Images: only author-written alt text is indexed, never OCR. Speaker notes off by default. 500-slide limit. |
| CSV | Enabled by default | yes | no | Comma, semicolon or tab separators. Limits: 100,000 rows, 256 columns, 10,000 characters per cell. One "column: value" unit per row. No tabular computation by default. |
| Markdown (.md) | Enabled by default | yes | partial | Recognised by the .md/.markdown extension only. Headings, lists, tables and code fences kept as typed blocks; inline HTML neutralised; links never followed. 2,000,000-character limit. |
| HTML | Enabled by default | partial | partial | Treated as hostile: scripts, styles, iframes, SVG and forms removed; no external resource loaded. Table rows flattened to text. 2,000,000-character limit. |
Charts (curves, diagrams) are not recognised: only native Office chart data can be extracted, behind a flag disabled by default.
DXF, DWG, IFC: documentary support, not graphical interpretation.
| Format | Status | Text | Geometry | Metadata | Limits |
|---|---|---|---|---|---|
| DXF drawing (.dxf) | Configurable | yes | no | yes | Closed by default (dxf_ingestion_disabled); the Compact configuration does not open it. Documentary support: annotations (TEXT, MTEXT, dimensions), block attributes, layers and declared references. Geometric entities are only counted: no coordinates indexed, no rendering, no interpretation of the drawing. |
| DWG drawing (.dwg) | Optional | yes | no | yes | Build option disabled in Compact (WITH_DWG=0). Converted to a temporary DXF by LibreDWG (GPL, compliance review required by the documentation) then same documentary scope as DXF; AutoCAD 2000-2018 versions only. |
| IFC model (.ifc) | Optional | yes | no | yes | Build option disabled in Compact (WITH_IFC=0) and flag closed. Semantic extraction only: spatial hierarchy, elements, properties, quantities, materials; no geometry, no rendering. Requires a dedicated worker. |
| SVG (as plain text) | Not yet qualified | partial | no | no | No dedicated extractor: the file is classified as plain text and indexed as is (markup or structure included). Not tested; retrieval quality not guaranteed. |
The audio ingestion code exists; the transcription engine does not.
| Feature | Status | Description and limits | Details |
|---|---|---|---|
| Audio ingestion and transcription via the gateway | Optional | /documents/upload-audio/ (mp3, m4a, wav, flac, ogg, webm; ≤600 MB; ≤12 h), ffprobe/ffmpeg → 16 kHz FLAC in ≤90 min parts → asynchronous Gateway ASR job (asr-whisper-turbo); ≤1000-char units with time_range. One ASR job in flight per environment; no error rate measured; transcript never numeric proof; no audio player. | Details
|
| Multilingual transcription | Not yet qualified | Language auto|fr|en in the ASR contract; announced languages fr/en; quality not measured. No particular limit noted. | Details
|
| Gateway speech-to-text (ASR) endpoints | Disabled | POST/GET/DELETE /v1/audio/transcriptions (multipart, json|text|srt|vtt, language auto|fr|en, diarize, 202 jobs) relayed to an external faster-whisper backend on 127.0.0.1:8400 that is not shipped; disabled (503 asr_unavailable). The gateway never decodes audio; the ASR backend is not part of the Open distribution. | Details
|
| Audio in the Compact profile | Disabled | Audio disabled: WITH_AUDIO=0, DOCUMENT_AUDIO_*=0, AI_GATEWAY_ASR_ENABLED=0, no ingest_audio worker; E2E qualification expects audio upload refusal. No particular limit noted. | Details
|
| Speaker diarisation private edition only | Unavailable | Requested by RAGatm (diarize=true, ≤4 speakers, speaker_00… labels) and declared in the Gateway registry vocabulary; the backend (Sortformer) is not included. No particular limit noted. | Details
|
Each option implies an image rebuild or an extra component, and none is covered by the Compact qualification.
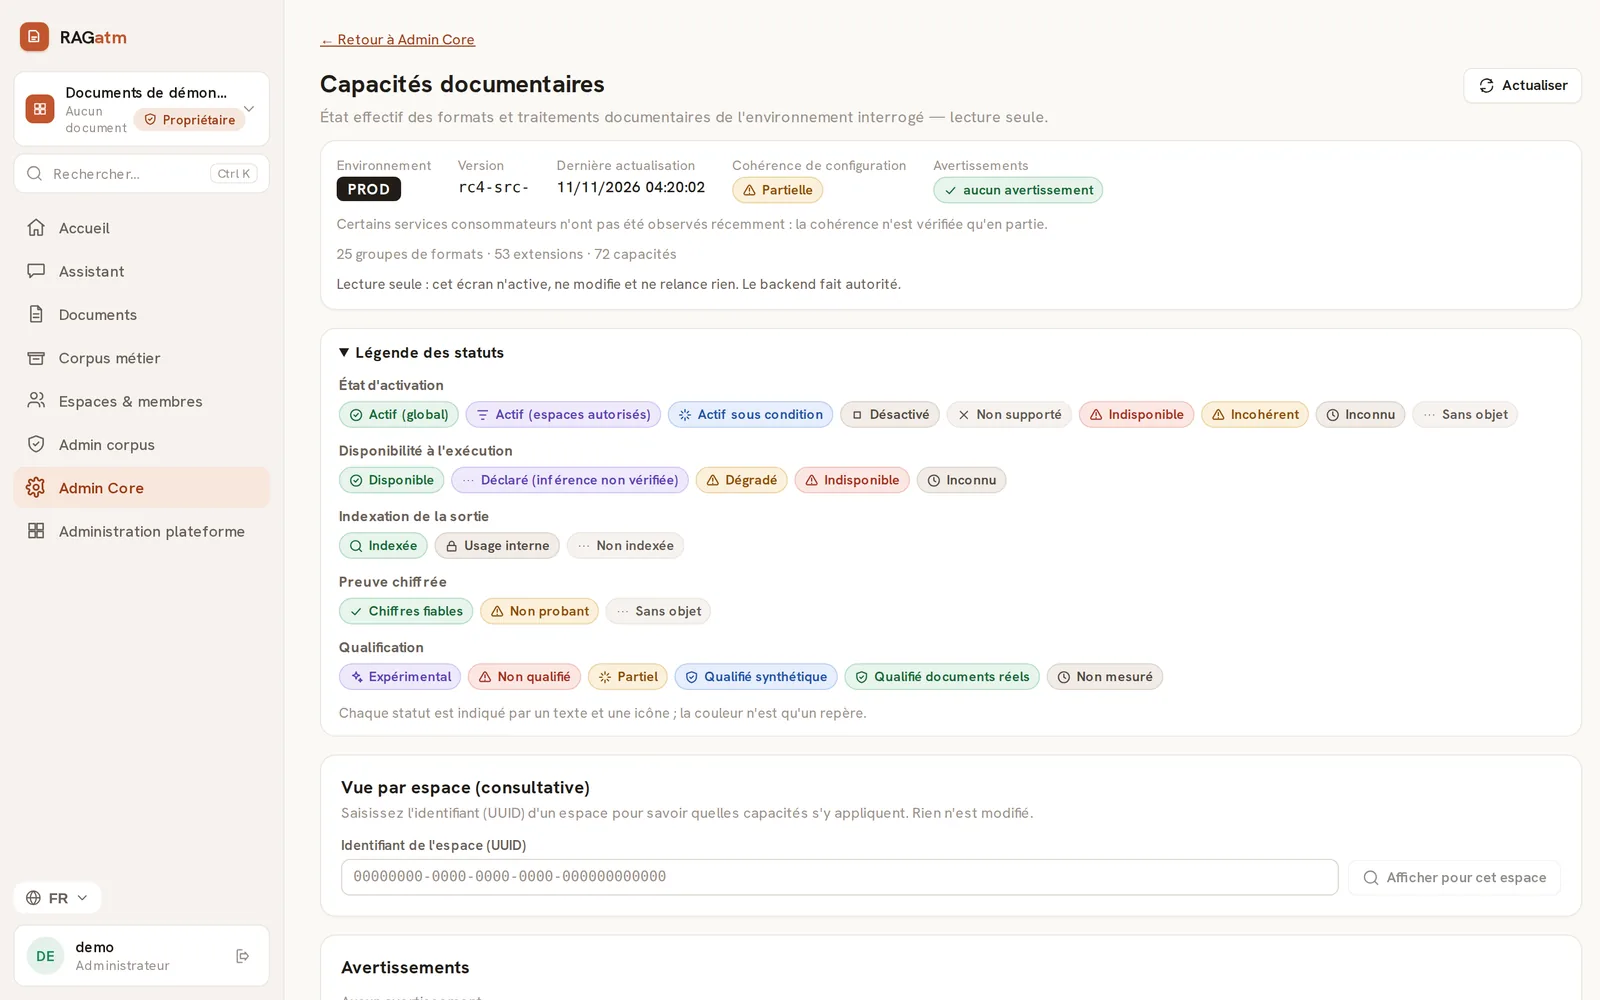
Screenshots taken on an isolated RAGatm Open instance (Open edition, Compact profile on CPU, reranker disabled for the capture), with the fictitious documents published in the repository and a demo account.